

On September 8, 2026, Google DeepMind released "AlphaGenome Atlas," a collection of predicted molecular effects for roughly 9 billion possible single-nucleotide variants in the human genome. Previously, researchers had to run an AI model for each variant of interest. Now they can search precomputed results and see which variants to examine first, and why. The data totals 1 petabyte and is available for non-commercial research use. What researchers gain is a guide for choosing the next experiment from a vast pool of candidates. To judge how useful it is, computational predictions must be kept separate from phenomena confirmed in experiments.
What the 9 billion figure counts
The Atlas covers single-base substitutions at positions with a determined base in the human reference genome GRCh38. Each position in the DNA is changed to each of the three bases other than the original. With about 3 billion bases and three possible substitutions each, the total comes to about 9 billion. It is not the number of people whose DNA was measured, and it does not mean the DNA of everyone on Earth was sequenced one by one.
The calculations use AlphaGenome, which takes in roughly 1 million surrounding bases and predicts how genes behave. The team compared predictions for the original and the mutated sequence to estimate effects such as how much a gene is read out and how RNA is spliced. The Atlas also includes more than 100 million observed short insertions and deletions, but this does not mean it covers every kind of large-scale structural change in DNA. According to the technical paper, each variant is associated with an average of about 27,000 predicted values. That is a count of computed values across cell types and measurement targets, not a count of experiments.
The AlphaGenome Variant Impact (AVI) score is what makes this volume of values practical for choosing candidates. It combines AlphaGenome's predictions with other information, such as AlphaMissense, which handles variants that alter proteins, and evolutionary conservation, to rank variants. It can also trace how much features such as RNA processing contributed to a score. A high rank is a lead for further investigation, but it does not directly represent the probability of disease.
The stages of publication also differ. The foundation model, AlphaGenome, was published as a peer-reviewed paper by Žiga Avsec and colleagues in Nature on January 28, 2026 (DOI: 10.1038/s41586-025-10014-0). The Atlas, by contrast, rests on a new technical paper by Jun Cheng and colleagues, which Nature's September 9 report describes as a preprint. The peer review of the foundation model and the validation status of the Atlas's new analyses should be treated separately.
Confirming an RNA abnormality in an epilepsy case
In a collaboration with the GREGoR Consortium, researchers examined small variants absent in the parents among 814 individuals for whom genomic data from both parents and the affected person were available. In one case of epileptic encephalopathy, the top-ranked variant by AVI was in a non-coding region of the DNM1 gene. Even in places that do not directly specify a protein sequence, a variant can affect the resulting protein if it alters RNA processing.
AlphaGenome predicted that this variant would shift the splicing position, where RNA is cut and joined, making the protein 13 amino acids longer. The prediction applied to a transcript used in the brain; it also indicated that the relevant segment is barely read out in blood. This is a hypothesis that could explain why earlier RNA analysis of blood was inconclusive, but it is not the result of measuring the patient's brain directly.
The team therefore introduced the variant 265 bases upstream of the relevant exon 10a and ran a minigene experiment measuring RNA processing. According to the main text, the experiment used five cultured cell lines, and the methods section states that each condition had three biological replicates, with RNA extracted 48 hours after introduction. The experiment confirmed 12 variants that extend the exon while preserving the protein reading frame, and the team compared these against the predictions.
What this experiment directly supports is a splicing abnormality in the cells and sequences tested. The authors also discuss, as a possibility, a mechanism in which the abnormal protein interferes with the function of normal protein in the brain. The same 13-amino-acid extension has been reported in two earlier cases, and taking this evidence together, the authors recommend classifying the variant as "likely pathogenic." This was not a trial showing therapeutic benefit, nor did it demonstrate the accuracy of Atlas-based diagnosis in general.
What did the "22% increase" actually increase?
The population analysis, led by Gareth Hawkes and colleagues at the University of Exeter, covered 54,189 people in the UK Biobank and 2,028 proteins measured in blood. It grouped non-coding variants with a frequency below 0.1% and tested their statistical associations with protein levels. The question was whether narrowing to variants in the top 1% for each Atlas feature could pick up associations that had been hard to see when variants with different effects were lumped together.
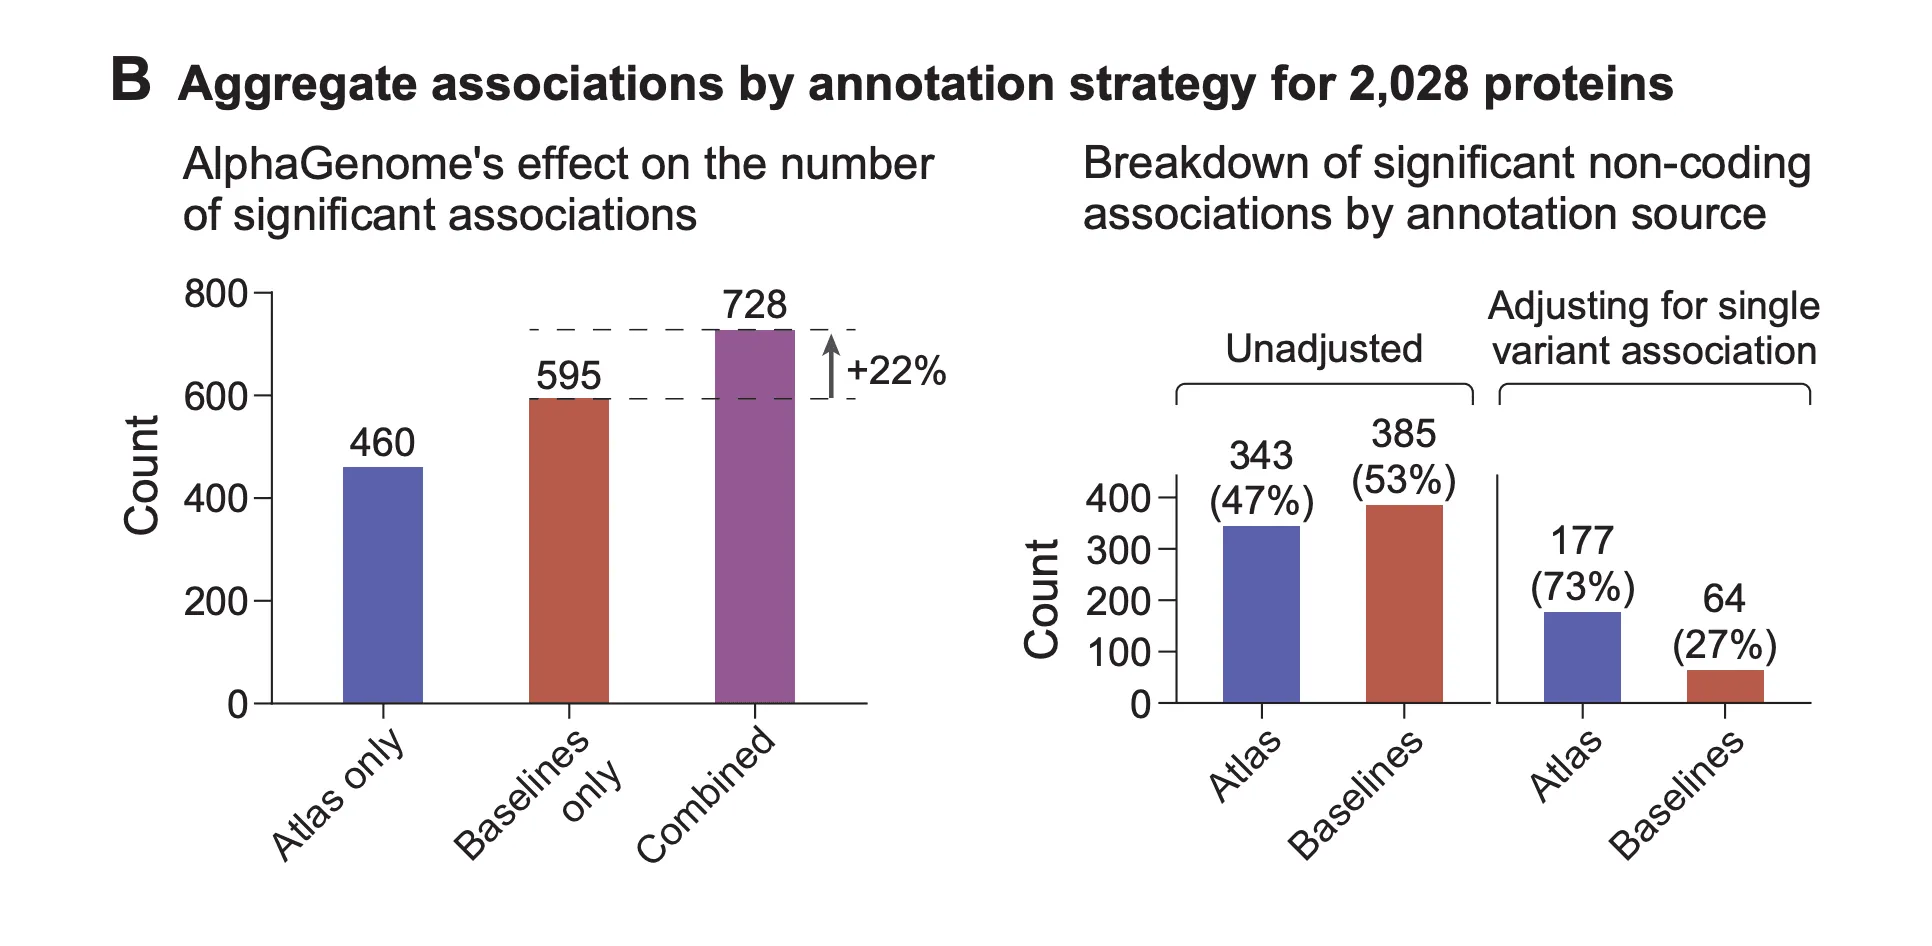
The "22% increase" in the official announcement is neither the share of diseases identified nor an increase in protein levels. In Figure 4B of Cheng and colleagues' paper, after adjusting for the effects of common variants and other factors, the authors compare the number of significant associations deemed independent in conditional analysis.
| Variant set used in the analysis | Number of significant associations |
|---|---|
| Variants selected by existing methods only | 595 |
| Variants selected by the Atlas only | 460 |
| Both variant sets combined | 728 |
Figure 4B (page 11 of the paper) compares the same targets. The rise from 595 to 728 works out to about 22%, using (728 − 595) ÷ 595 × 100. The Atlas-derived set alone yielded 460, so what this result supports is additional discoveries when used together with existing methods. Even if narrowing candidates through prediction helped, it does not mean each association found was demonstrated as a cause of disease.
There is also a caveat about the version of the Atlas used. Because the UK Biobank analysis platform was temporarily suspended in April 2026, the paper's main results came from an internal version that predates the public release. The authors expect the effect on their conclusions to be small based on preliminary comparisons, but they do not report having completed an update with the public version. It is premature to treat the announced figures as results that users of the public version can reproduce as they stand.
From choosing candidates to independent validation
The Atlas is available through a web portal, an API, and features for Google Antigravity. Non-commercial access has begun, and commercial availability of the Atlas through Google Cloud is planned for the future. If the burden of repeating the computations in each lab falls, researchers should find it easier to devote time to comparing candidates and designing experiments.
However, the training data lacks some cell types, and the model does not directly account for effects arising when the levels of other regulatory factors change. The paper also explains that correspondences between short DNA sequence patterns and function depend on predictions and do not necessarily indicate direct causal relationships in living organisms. On using the tools within the body of evidence for clinical diagnosis, the authors write that the Atlas and AVI are "not sufficient evidence on their own."
Nor can the cell experiments or similar case reports in this work be equated with independent replication of the Atlas's overall performance. No such replication can be confirmed in the public materials, and the authors themselves say that assessing reproducibility for ultra-rare variants is difficult. What researchers need to confirm next is whether highly ranked variants behave as predicted in the relevant cells, and whether population-level associations replicate in other datasets. If such validation accumulates, the vast set of precomputed predictions could be turned into experiments that uncover how diseases work.