

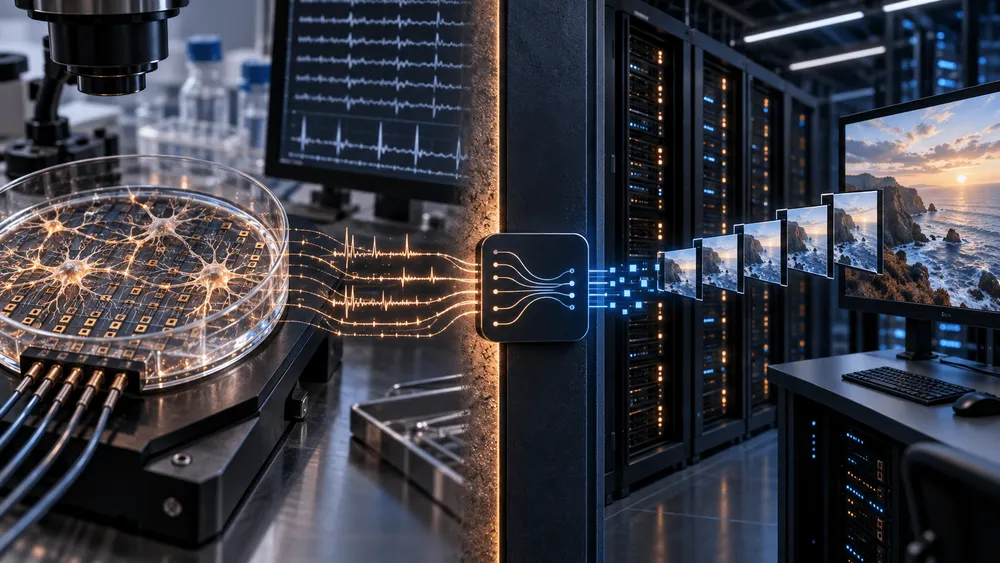
The Biological Computing Co. (TBC) and Amazon Web Services (AWS) announced on September 22 a collaboration to commercially offer, through AWS, a video generation AI improved using the responses of cultured neurons. TBC claims the model generates video five times faster than a conventional model and cuts inference costs by 80%.
However, the company has not disclosed which model it compared against or under what measurement conditions. The Minecraft-style video demonstration released in July also does not necessarily serve as a test that directly supports the "5x" and "80% reduction" figures.
To understand this announcement, it helps to separate two things: software built on the responses of cultured neurons, and the delivery and inference techniques used to speed up generation.
AWS will offer a video generation model, not cells
According to the joint announcement, what TBC aims to provide is a text-to-video generation service based on an improved existing open-source model.
Insights gained from cultured neurons are incorporated into a proprietary software layer, and the additional parameters amount to less than 0.1% of the original model, the company says. Users do not need to set up facilities for growing neurons. The computation for actually generating video runs on ordinary AI computing infrastructure.
The AWS collaboration includes running on its custom AI chip Trainium, offering the model through Amazon SageMaker AI, and selling it on AWS Marketplace.
However, the announcement describes all of these as future plans, and what is currently available is a sign-up for early access. Pricing, the general availability date, supported resolutions, and the length of video that can be generated have not yet been made public.
As a result, there is not yet enough information to translate the "5x faster" claim into the wait times users will actually experience or the fees companies will pay.
What has changed is less the technology itself than the stage of commercialization.
On July 30, TBC showed a public demo using Oasis, a world model that generates Minecraft-style scenes one frame at a time in response to player input. This time, the company aims to use AWS's sales and delivery infrastructure to deploy a commercial text-to-video model for a different purpose.
The public Oasis demo and the model now headed for commercialization cannot be treated as the same product or the same performance test.
How are neuronal activity patterns brought into software?
TBC grows neurons on a chip with 4,096 electrodes and records their responses to electrical stimulation.
It measures not only where stimulation is applied but also how far neural activity spreads to surrounding areas and how quickly it fades. Features obtained from these measurements are quantified and reflected in the design of small add-on modules that act on the intermediate representations of a video generation model.
Cultured neurons are used at this design and training stage. Living neurons are not connected when the finished model actually generates video.
The first one released, the "Neural Dynamics Adapter," is a mechanism that adds local spatial information to the early layers of the diffusion Transformer responsible for image prediction in Oasis.
It adds roughly 156,000 parameters. The original model itself is also further trained at a low learning rate, so this is not a simple setup in which numbers measured from neurons are fed into the model to improve performance.
It is software that uses features derived from neuronal responses as clues for design and is then tuned with video data.
The later "Hypercolumn Neural Optimizer" (Hypercolumn version) combines convolution operations that mix information from nearby locations with a mechanism that retains past information at each position.
TBC measured how far neural activity spreads in space and how much it decays over time, and reflected those features in the respective processing designs.
This version adds about 14 million parameters, roughly 3% of the original model. It differs greatly from the first small adapter in both function and scale.
The commercial model and the public demo are not the same performance test
The figures TBC has published so far come from different models and tests. Organized by target, they look like this:
| Target | Added mechanism and test | Published result |
|---|---|---|
| Commercial model for AWS | Text-to-video model whose base model has not been disclosed. The added layer is under 0.1% of the original model | TBC claims 5x generation speed, 80% lower inference cost, and improved quality versus a baseline model |
| Oasis small adapter | About 156,000 parameters. Evaluated on 10 videos using different starting scenes and actions | TBC reports about a 19% improvement over the original model on a proxy metric measuring the information retained in images |
| Oasis Hypercolumn version | About 14 million parameters. Evaluated on 200 action sequences of 600 frames each | TBC reports comparisons with the original model on five metrics at the 10-second mark, and a 4.4x single-stream generation speed |
The basis for the comparison is the announcement of the commercial model and the technical explanations TBC published for the small version and the Hypercolumn version.
It cannot be confirmed that the commercial model's base model and input conditions are the same as those in the Oasis experiments. The scale of the added layers also differs.
Therefore, the "4.4x" figure from the public demo cannot be treated as a directly measured value supporting the "5x" claim for the newly announced commercial model.
The "about 19% improvement" reported for the small version is also not a score that directly represents overall video quality.
TBC indirectly evaluated how much information in the images is lost, using a statistical measure of information content, across 10 continuously generated videos.
The company also reported that the result was about 15% better than ordinary fine-tuning with a comparable number of added parameters, and about 5% better than tuning with LoRA. All of these, however, were obtained under this particular test setup.
Furthermore, the body text and figure caption of the technical blog are inconsistent about whether a higher or lower value is better for that statistical measure. It is difficult to judge from a single improvement rate whether image quality would actually look better to human viewers.
In the announcement of the public Oasis demonstration in July, the company said it ran an external test under matched conditions with AI infrastructure company Bluesky Compute, and that the selected image quality metric doubled, inference cost fell to about one-fourth (roughly 4.4 times lower), and the duration over which consistent video could be generated increased more than threefold.
However, the GPUs used, the resolution, how costs were calculated, and how video consistency was judged have not been disclosed.
Although an outside company was involved in the test, it should be considered separate from a public benchmark that third parties could reproduce under the same conditions.
The 4.4x speedup is not due to the adapter alone
The roughly 4.4x speedup reported for the Hypercolumn version was not achieved simply by adding a neuron-derived adapter.
According to TBC, a single stream that ran at about 2 frames per second in the original serving configuration was raised to nearly 10 frames per second after the improvements.
This combined a cache that reuses past computation results, a sampler that generates images in fewer steps, and a mechanism that processes multiple users in parallel across several GPUs.
In video diffusion models, generating a single frame normally involves repeating a process of gradually removing noise many times. Reducing the number of steps speeds things up, but the video is more likely to break down.
TBC explains that the adapter, designed on the basis of neuronal responses, helps preserve image structure over long durations, allowing quality that normally requires 10 steps to be maintained with just 6.
In other words, the explanation is not that the biologically derived design directly cut the computation to one-fifth, but that suppressing quality degradation made it possible to use more aggressive speedup settings.
However, the published results alone do not allow us to separate how much each technique contributed to the speedup.
The individual effects cannot be known unless the adapter alone, the cache alone, and the sampler change alone are compared on the same hardware and against the same quality standard.
Also, "5x faster" and "80% lower inference cost" are not necessarily two independent improvements. In an environment where cost is proportional to processing time, cutting processing time to one-fifth would cut cost to about one-fifth as well.
The two figures should therefore not be added together when evaluating the model.
What should be compared to judge commercial value?
TBC's public experiments demonstrated a concrete method for incorporating features obtained from the stimulus responses of cultured neurons into the design of a video generation model.
On the other hand, the evaluations so far have mainly targeted a single Minecraft-style environment, and it has not yet been confirmed whether similar effects can be obtained in general text-to-video generation.
TBC itself lists as future challenges whether results can be reproduced across different environments, actions, and inference conditions, and quantifying the amount of energy required.
The materials published so far are also company technical blogs and announcements, not peer-reviewed papers.
What companies considering adoption will want to know is how much time and cost can be saved when generating video of the same length, at the same resolution, and with comparable quality.
If the name of the base model, the GPU or Trainium used, the number of sampling steps, and how failed generations were handled were disclosed, the "5x faster" and "80% reduction" figures could be evaluated in a form closer to actual operation.
To evaluate the value of the neuron-inspired design itself, it would also need to be compared with ordinary adapters of similar scale and with existing acceleration methods. A fairer assessment would also include the computation and cost required to train the model.
Living neurons are not directly generating video inside a data center.
Still, if incorporating features derived from neuronal responses into AI design can repeatedly deliver a balance of image quality and speed that was difficult with conventional methods, there would be a point in using cultured neurons as a guide for AI design.
If specific usage terms and reproducible comparison results are published for the commercial model to be offered on AWS, it will become possible to evaluate more concretely how useful this technology is in actual video generation.