

On November 19, 2026, AMD and Unsloth announced that Unsloth Desktop now supports local inference on AMD's XDNA 2 NPU. On compatible Ryzen AI PCs, apps such as AI agents can use AI models running on the PC itself through the Unsloth Desktop API. According to AMD, the apps and workflows that can connect number more than 100 in total.
This is the first time Unsloth Desktop has supported an NPU. By offloading inference to an NPU, which is specialized for AI computation, a PC can run AI models while the GPU stays free for tasks such as video processing. However, which models are available depends on the NPU generation and supported model formats, and the memory required for inference must also be taken into account.
Inference is handled by the PC's built-in NPU
AI agents carry out their next steps based on responses they receive from an AI model. In this setup, Unsloth Desktop's OpenAI-compatible API serves as the entry point for inference requests. On the PC, Lemonade relays requests to the model, and FastFlowLM runs inference on the XDNA 2 NPU. Results are returned to the app via the Unsloth Desktop API. Because the OpenAI-compatible API is used, each app does not need to implement NPU execution on its own.
AMD named Hermes Agent, OpenClaw, and Open WebUI among the compatible apps. They also include the coding assistants Cline and GitHub Copilot, as well as the application development framework LangChain. The figure of more than 100 refers to the combined number of apps and workflows that can use models running on the NPU through the API. Controlling tool calls and follow-up processing based on the model's responses remains the job of each app.
Unsloth showcases a use case in which a chat AI model runs on the NPU while a Radeon GPU renders video. AMD explains that shifting inference to the NPU reduces power consumption and makes it easier to use the CPU and GPU for other work. However, running other tasks on the GPU at the same time requires sufficient memory headroom. AMD's technical blog also cites available memory capacity as a condition for allocating CPU and GPU resources to other apps.
Different setup requirements on Windows and Linux
Unsloth lists the Ryzen AI 300, Ryzen AI Max, and Ryzen AI 400 series, equipped with an XDNA 2 or later NPU, as supported products. Ryzen AI 300 includes Strix Point and Krackan Point, Ryzen AI Max includes Strix Halo, and Ryzen AI 400 includes Gorgon Point. According to Unsloth's official guide, both Windows 11 and Linux are supported, and only x64 environments are targeted.
AMD's technical blog walks through setup on Windows, but the NPU can also be used on Linux. The US tech outlet Phoronix reports that it confirmed with AMD in advance that the Ryzen AI NPU works with the Linux version as well. According to Unsloth's official guide, on Linux you use the amdxdna driver included in kernel 7.0 and later, or amdxdna-dkms for older kernels. You also need to update the NPU firmware and set memlock, which defines the upper limit of memory a process can lock, to unlimited.
On a compatible PC, you can filter for NPU-compatible models from the model selection screen in Unsloth Desktop. During initial setup, selecting "Enable NPU" prompts Unsloth to download FastFlowLM and check the NPU driver version. Once setup is complete, you can find FastFlowLM-compatible models using the NPU filter in the model hub, then download and use them.
Shared memory capacity determines which models you can run
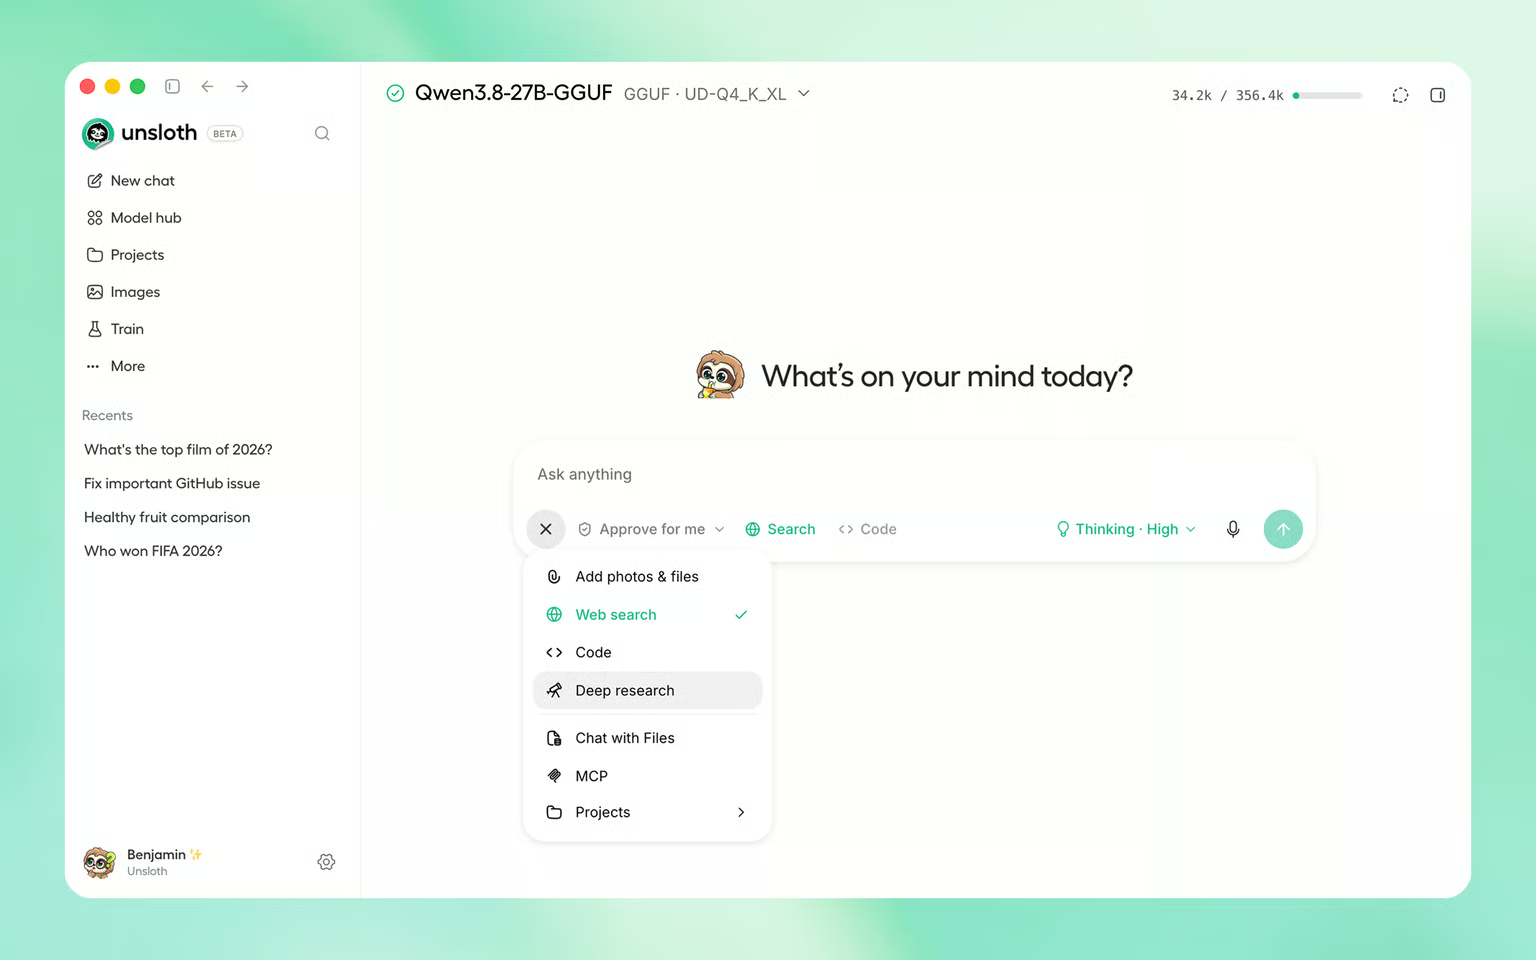
The models that can run on the NPU are those that support "Q4NX," a 4-bit quantization format for FastFlowLM. Quantization is a technique that reduces data size by representing a model's weights with fewer bits. In actual inference, however, memory is needed not only for the model weights but also for holding input data and conversation context. Being able to store a model's distribution files is therefore a separate condition from being able to run inference at the desired context length.
Unsloth publishes the distribution size and recommended system RAM for each supported model. For example, Qwen3.6-35B-A3B-NPU2 has a distribution size of 20.6GB and a recommended 64GB of RAM. Qwen3-VL-4B-Instruct-NPU2, on the other hand, has a distribution size of 3.9GB and a recommended 16GB of RAM. As these examples show, the memory required varies widely by model. Support for images, audio, and tool calling can also be checked in the model list in Unsloth's official guide.
AMD used Qwen3.6-35B-A3B, a mixture-of-experts (MoE) model with 35 billion total parameters, in its demonstration. Running it at the maximum context length requires about 28GB of memory available to the NPU. AMD's technical blog states that Windows allocates 50% of system memory as shared memory by default, and points to a PC with 64GB of system RAM as a configuration that meets this requirement. In other words, the roughly 28GB is the capacity needed for NPU inference, while 64GB is the total installed capacity of the PC once the shared-memory allocation is taken into account.
By default, Unsloth Desktop's automatic setting determines the context length based on the free RAM at the time the model is loaded. You can also set the context length manually before loading the model. For example, if you have an AI agent process a long document while rendering video on the GPU, what matters is whether you can secure the required context length and memory capacity with both apps running.