Tech
AMD and Cerebras Split AI Inference Duties, Aiming for Lower Latency with Helios and WSE
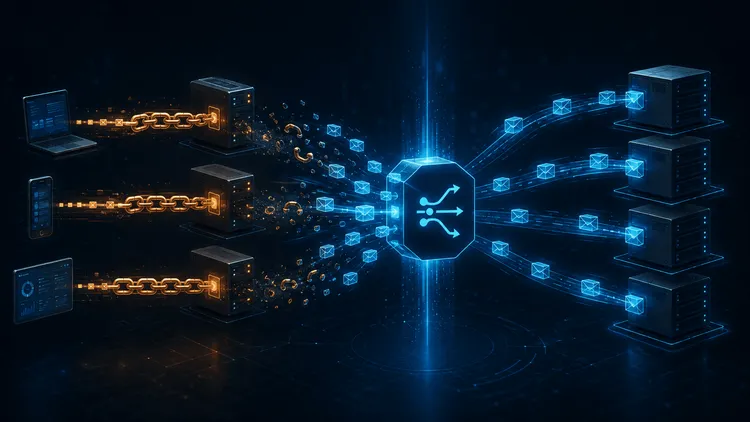
AMD and Cerebras plan to launch a division-of-labor AI inference platform in the second half of 2026, with Helios handling input processing and WSE handling token generation. The claimed up-to-5x figure comes from internal modeling comparing against WSE alone, and disclosure of measured latency and pricing will be the next thing to watch.