

On September 15, TypeSafe AI announced early access to its "System One" model class, which returns decisions that software can use directly, along with its first public model, "Jev." Jev does not generate free-form text. Instead, it returns answers and probabilities for predefined options and rating scales. Pricing is $0.042 per million input tokens, with no charge for output, and the company claims a 193.6x speedup in its own business-workflow evaluation. However, the comparison covers specific decision tasks, and it does not mean Jev matches general-purpose intelligence. The place to start in understanding Jev is what changes when text generation is given up, and how much automation can be entrusted to it.
Dropping free-form text and handing decisions back to software
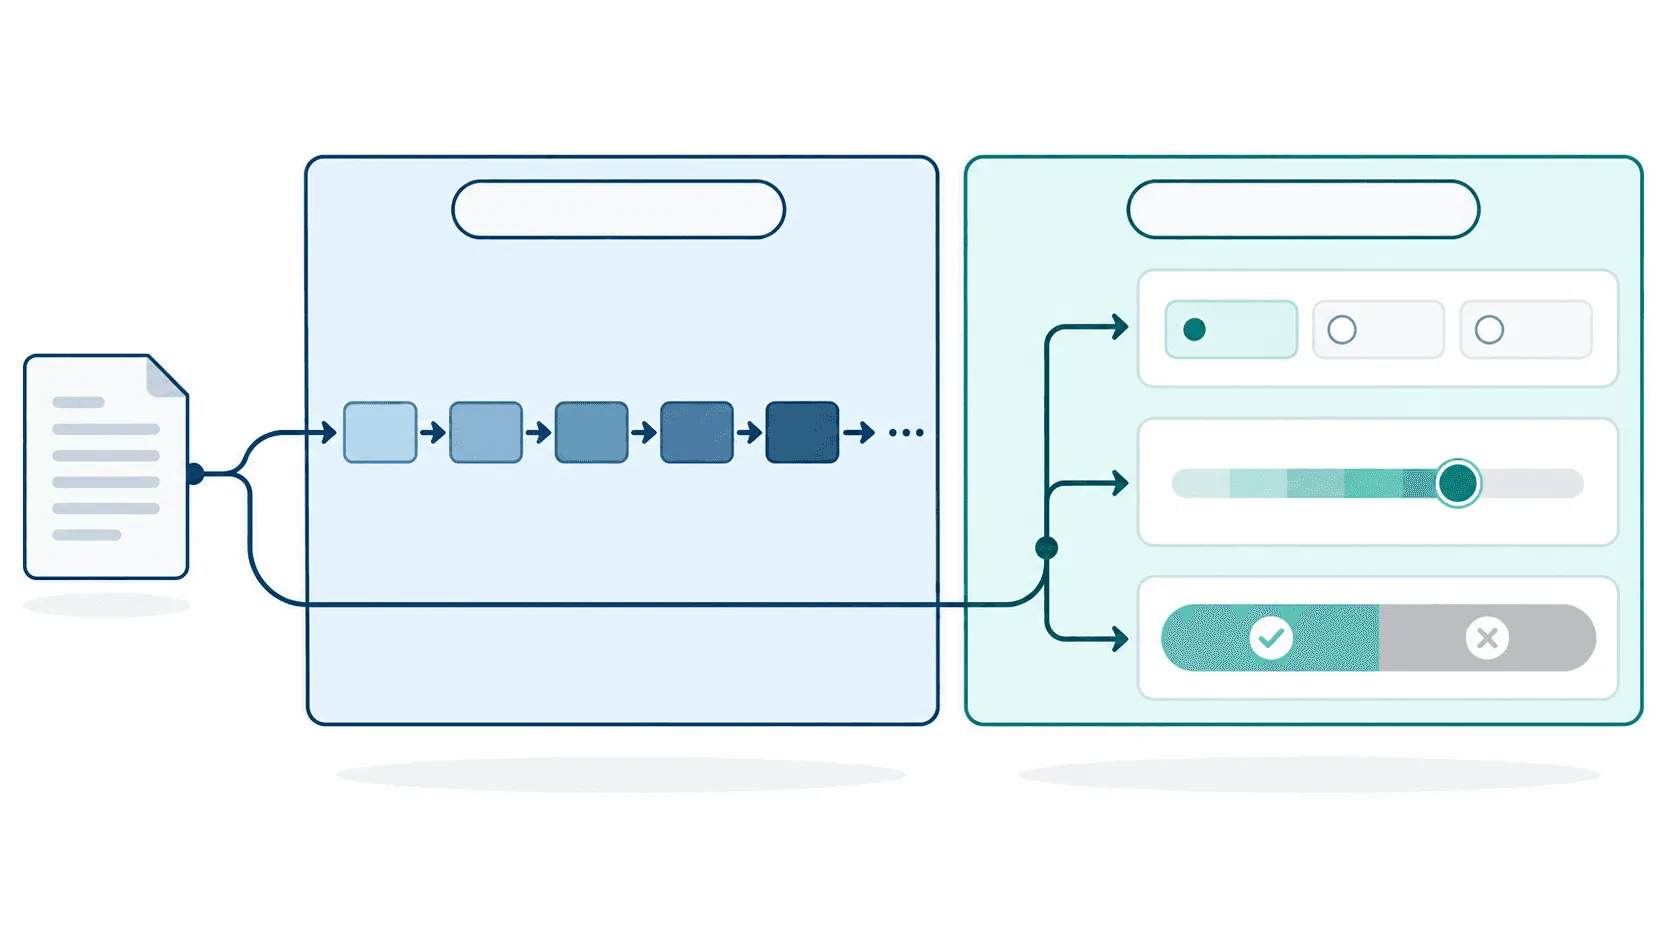
Jev's input consists of a state, which bundles the material for the decision, and questions, which ask about that material. The input can be just the text of an inquiry, or data that adds order information and internal policies to a conversation history. Multiple questions can be sent against the same material, and each is evaluated independently. The design uses natural-language understanding but skips the step of turning the response into conversational prose.
The official documentation defines the question formats developers use as follows.
- Choice selects from a set of candidates you provide. For a question such as "Is the responsible department billing, technical, or accounts?", it returns the selected option, probabilities for all candidates, and a confidence value. The limit is 255 candidates.
- Score evaluates along levels you describe in words. The number of levels ranges from 2 to 10, and it returns a probability for each level plus a weighted average of the level numbers.
- Noul answers a question such as "Is the customer requesting a refund?" with the probability, from 0 to 1, that the answer is "yes." It has no separate confidence field.
A Score value differs somewhat from a score the model invents freely. Suppose, for example, you define the severity of an outage on levels 0, 1 and 2, and the probabilities are 0, 0.70 and 0.30. The result is 0×0 + 1×0.70 + 2×0.30 = 1.30. The user defines the scale, and the position on that scale is computed from the probabilities. It is not a figure showing what share of customers were affected by the outage.
With this design, you don't need to hand the AI a large instruction like "process the refund" in one piece. You can ask separately whether a refund was requested, whether the description indicates a duplicate charge, and whether the case fits the policy, then combine the answers in code. Amount calculations and the conditions for executing a process can sit in ordinary programs. TypeSafe's aim is to use AI judgment as a component of software.
The name System One comes from Daniel Kahneman's distinction between fast, intuitive thinking and slower, deliberate thinking. It is not a claim to have reproduced how the human brain works. The official documentation also recommends breaking tasks into questions a person given the right information could answer quickly, rather than asking for long reasoning in one pass.
How is it different from LLMs that support structured outputs?
Existing large language models (LLMs) also have mechanisms that strictly constrain the shape of their output. OpenAI's Structured Outputs, announced in August 2024, narrows the tokens that can come next to match a developer-specified JSON Schema. Under supported conditions, excluding cases such as refusals and truncated generation, it guarantees output that fits the specified format. That is different from simply asking the model to "answer in JSON."
Therefore, describing Jev's difference as "LLMs can only return prose, and only Jev keeps to a format" misses the point. The comparison that matters is between a mechanism that generates text under constraints and a mechanism specialized in returning constrained decisions.
| Point of comparison | Primarily autoregressive LLMs | Jev / System One |
|---|---|---|
| How output is produced | Generates the next token in sequence, based on prior output | According to the company, returns answers and probabilities to multiple questions in parallel |
| Format constraints | On supported models and APIs, generation candidates can be restricted to guarantee schema conformance | Possible answers are defined in advance with Choice, Score and Noul |
| Free-form writing | Can generate prose, code and explanations | Does not generate reply text, code or explanations of its reasoning |
| Assembling complex work | Combines model reasoning with tools and code | Breaks work into narrow decisions; combining results and branching the process are decided in code |
The LLM column in the table is based on OpenAI's explanation of constrained generation, and the Jev column on TypeSafe's announcement and model specification. It does not classify every language model under one method; it compares free-form capability with a decision-specific design.
In an autoregressive model, even writing a probability distribution out as JSON means generating values and delimiters one after another. Jev gives up that freedom and, by handling multiple answers in parallel, is said to shorten waiting time. Because many decisions can be asked at once, the number of individual calls also falls. However, adding questions costs input tokens, so increasing volume does not keep costs constant.
There are limits to what is publicly known about the internal model structure. TypeSafe says it developed a new architecture and a parallel sampler, and does not position Jev as a "small LLM." But the announcement and technical documents do not reveal the parameter count or layer configuration. It cannot be asserted that Jev does not use a Transformer, or that all processing finishes in a single operation. What can be compared in detail at present is the published inputs and outputs, the processing method, and the training objective.
RLCD teaches the "right answer" and uncertainty together
TypeSafe founder Diogo Almeida is a co-author of the 2022 InstructGPT paper. That research showed a method of tuning a model on human-written answer examples and then training it using human-assigned rankings of answers, that is, reinforcement learning from human feedback (RLHF). A researcher involved in developing instruction-following conversational models has now set a learning objective around decisions for software.
In RLHF, which answers people prefer guides the learning. By contrast, reinforcement learning with verifiable rewards (RLVR) uses tasks whose correctness can be checked by a program. In the example from the DeepSeek-R1 paper, rewards are given by checking math answers or verifying code against test cases. The two differ in what guides the learning.
TypeSafe's RLCD stands for Reinforcement Learning for Calibrated Decisions, meaning reinforcement learning for decisions and probability calibration. According to the company, it optimizes the output probabilities against outcomes so that they can reflect uncertainty. The model is trained not only to return a likely answer but also on how confident it should be in that answer.
The meaning of calibration is easy to grasp by thinking of a weather forecast. If you collect many forecasts that assigned "80%" to an event and the event actually occurs about 80% of the time, the predictions and outcome frequencies line up. Being wrong in the remaining cases is not inconsistent with an 80% forecast. This is a different property from getting every individual answer right.
Calibration itself is not an idea that originated with Jev. The ICML 2017 paper by Guo et al. examined the problem that the predicted probabilities of neural networks diverge from actual correctness, and evaluated methods of post-hoc adjustment of outputs in image and document classification. TypeSafe's proposal is to build calibration into the training objective of a model that returns decisions.
However, the specific reward function, loss function and training scale for RLCD are not shown in the public materials we were able to confirm. The difference in aims can be explained, but we cannot verify under what conditions the method outperforms existing approaches. Nor is it a clean division in which models trained with RLHF cannot handle probabilities, or RLVR is necessarily slower. TypeSafe's training approach and the performance evaluations that back it should be read separately.
"Probability" and "confidence" are not the same number
Jev's Choice and Score return probabilities, which gives per-candidate probabilities, and confidence, which expresses confidence. The latter is a statistic that condenses into a number from 0 to 1 how strongly the probability distribution concentrates on one candidate. It is not simply the probability of the selected candidate under another name.
In TypeSafe's published example, the top probability in Choice is 0.60 while confidence is 0.39, so confidence cannot be read directly as the probability of being correct.
This becomes clear by checking the complex-query example in the Choice documentation, as viewed on September 16, 2026, against the definition of confidence. In one response routing an inquiry to a department, the returns department gets a probability of 0.60 and billing 0.38, with confidence at 0.39. There is a leading candidate, but probability is also split with another. It is an illustrative output, not a measured accuracy rate.
Overlooking this distinction invites misreadings such as "confidence of 0.9 means 90% correct." Moreover, the System One documentation states explicitly that calibration is measured over a population of predictions and does not guarantee the correctness of any individual one. The threshold for passing a case to automated processing must be set based on actual business data and the consequences of errors.
Noul has no separate confidence value to begin with. A 0.1 for "Is the customer requesting a refund?" means the probability of "yes" is low, not that "the model has lost confidence." A value near 0 is a strong no, and a value near 0.5 means yes and no are about equally likely. Applying the same threshold to every output would mix up these meanings.
The same caution applies to TypeSafe's claim of "no hallucinations." What the company guarantees in terms of form is that the model does not produce values outside predefined types or candidates. If only real departments are candidates, for instance, a fictitious department name will not appear. But misrouting a billing inquiry to the technical department can still happen while conforming to the type. Conformance to format, correctness of decisions, and calibration of probabilities are separate properties that should be verified separately.
How to read the "193.6x faster" evaluation
The figures TypeSafe touts, "193.6x faster and 1/444.6 the cost," come from the company's business-workflow evaluation. It covers security response and monitoring of AI-agent execution, as well as invoice processing and customer support, with each task weighted equally in the aggregate. The company itself caveats that this is on the larger side of improvements to be expected in real deployments.
The evaluation is not a comparison against human-assigned ground-truth labels. It runs GPT-6 Astra and Claude Fable 5.1 on high reasoning settings and uses the average of their answer probabilities as the reference value. Other models are evaluated at each provider's default reasoning setting. In other words, it tests how closely, and at what cost and time, a model can match the judgments of a group of powerful models. If the reference side is wrong, agreement with the reference diverges from real-world correctness.
Another factor is that the LLM side is also made to return structured decisions and probabilities compatible with Jev. TypeSafe explains that this approach tends to be slower and more expensive than having models choose answers without probabilities. The adapter released for comparison includes settings that use providers' structured-output features and a setting that switches between a probability distribution and a selected result only. This is a meaningful comparison for work that needs probability distributions, but the same multiples will not necessarily hold when only a single label is wanted.
The announcement gives response times of 70 to 500 milliseconds, and the public evaluation was reportedly measured mainly from a laptop on the U.S. West Coast accessing a service also on the West Coast. There are also demos where short inputs favor Jev. Latency from Japan, with long inputs, or including multi-step processing needs to be measured separately.
Pricing is $0.042 per million input tokens, or $42 for a billion tokens, with no output charge. This is the sales price shown to users, not evidence that computing resource consumption or cost has fallen by the same factor. TypeSafe also acknowledges that it will take time to show that the pricing is unsubsidized and sustainable.
Third-party trials show the speed advantage and a gap in accuracy at the same time. Dan Shipper's test, reported by Every, applied four kinds of checks to 12 examples combining normal text with text containing deliberately inserted flaws. Median processing time per document was 0.35 seconds for Jev and 8.83 seconds for Fable 5.1 on high reasoning settings, making Jev about 25 times faster. Estimated cost was about 1/580, but of seven intended flaws, Jev found six while Fable found all seven.
A small test on synthetic text cannot be extended directly to general accuracy. Still, it is a concrete example that the design of using fast, cheap decisions in volume has advantages, and that reasoning models that take on hard decisions retain a different role.
Decisions to delegate, and work to keep in code
Even though Jev does not generate free-form text, it can be used to extract email addresses and amounts from documents. The extraction method is different, however. In TypeSafe's official implementation example, regular expressions first find candidates in the document, Jev chooses the intended candidate, and finally code copies and formats the original string.
This method eliminates the path by which the model rewrites the digits of a chosen amount. On the other hand, room remains for missing a candidate or choosing a different amount. For targets where candidate extraction is difficult, such as personal names, the documentation explains that an existing roster, a named-entity extractor or an LLM must supply the candidates. In exchange for giving up free-form writing, the software side takes on the preparation of candidates.
Returning multiple questions in parallel is also distinct from finishing an entire business process in one pass. The company's invoice-processing evaluation uses seven rounds of questions split by topic. Items that code can compute, such as totals and dates, are left to code, and the AI's judgments are used for branching the process. Work in which the next question can't be determined without seeing the previous result retains its stages.
One division of labor is to run the narrow judgments Jev is good at first and route ambiguous cases to a reasoning model or a person. That arrangement can also make use of existing LLMs' ability to write text. One example is quickly checking an answer written by an LLM from several angles and re-examining in detail only the parts that look problematic. Every's trial also points to the possibility of building cheap checks into the middle of a workflow.
What to verify once early access broadens is how much errors fall, and how many cases remain eligible for automated handling, when low-confidence cases are screened out using each company's real business data. Latency including network time, and rework caused by misses, also belong in the cost. If those conditions are met, Jev could bring decisions that were previously skipped because of cost or slowness into everyday software processing.