

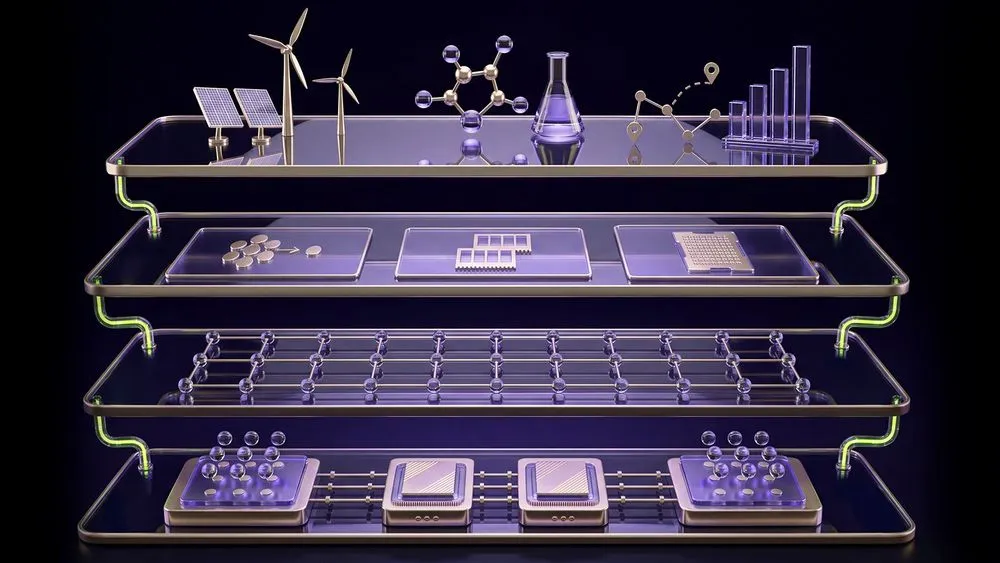
On September 14, 2026, NVIDIA added "CUDA-Q Logical," a design framework for fault-tolerant quantum computing, to its open-source CUDA-Q platform. It is a compiler framework that maps logical programs onto error-correcting codes, determines the placement and execution order of physical qubits, and connects through to classical decoding. This does not mean a practical-scale fault-tolerant quantum computer has been built, and the core paper published around the same time remains a pre-peer-review preprint. Even so, the announcement marks a shift—from discussing quantum computing progress purely in terms of qubit counts, to verifying under which assumptions, which circuits, and at what speed success can actually be achieved.
From P0 to P4: getting specific without discarding assumptions
In fault-tolerant quantum computing, a single logical qubit is encoded across many fragile physical qubits. But the number required is not determined by the code alone. If any of the following changes—how logical operations are decomposed, how ancilla states are supplied, how qubits are moved, how measurements are taken, how classical decoding proceeds, or the deadline for returning corrections—both the number of qubits needed and the execution time shift as well. In designs that manually stitch together specialized tools, it was easy to lose track of where assumptions and figures along the way originated.
CUDA-Q Logical addresses this disconnect by splitting the process into five stages. P0 represents a logical program independent of any device or code; P1 represents logical layout and resource provisioning without yet choosing a code. P2 selects the quantum error correction (QEC) code and operational procedures, and constrains detectors and retries upon failure. P3 defines physical resources and device-specific operations, incorporating noise and timing to build an execution schedule. P4 handles instruction dispatch, transfer of measurement results indicating error syndromes, decoding deadlines, and feedback to the quantum side.
The key point is that it doesn't compress all conditions into a single number too early. While keeping the same P0 program intact, you can swap out the code, decoder, execution method, and hardware description at typed boundaries. When two estimates differ, it becomes easier to trace whether the cause was a rewritten algorithm, a changed error-correction scheme, or altered device constraints.
That said, what the paper demonstrates is compiler transformation, model verification, and simulation. Even if conversion from P0 to P4 succeeds correctly and produces an executable schedule, that doesn't mean it's the optimal design, nor does it guarantee accurate prediction of future hardware performance. arXiv:2609.13388 is a working draft submitted on September 11, 2026, with all authors affiliated with NVIDIA. Third-party peer review and reproduction on different hardware are still to come.
Breaking one estimate into four
CUDA-Q Logical's official documentation divides resource estimation into four tiers: LOGICAL, STATIC, ANALYTICAL, and SCHEDULE. All four can target the same program, but they answer different questions.
| Estimate | Stage and assumptions required | Main output |
|---|---|---|
| LOGICAL | P0. Neither device nor code selected | Number of logical operations, number of logical qubits, operations requiring synthesis |
| STATIC | P2. Code, encoding, and operation sequence selected | Post-encoding operations, resources, number of measurements for error detection |
| ANALYTICAL | P2 plus physical error rate and timing model added | Logical error, acceptance rate, time, number of physical qubits, retries |
| SCHEDULE | P3. Physical events and dependencies made concrete | Time required, resource occupation time, utilization |
CUDA-Q Logical's four-tier resource estimates return, for the same program, separate figures for: logical operations before an error-correction scheme is chosen, static counts based on the selected code and procedure, analytical values with physical assumptions applied, and time-required and utilization figures derived from a physical schedule. The more detailed the numbers, the more assumptions are layered in.
So it's not that SCHEDULE values are "more correct" than LOGICAL ones. The former answers a more device-specific question in greater detail, but is also more tightly bound by inputs such as error rates, operation times, connectivity, and movement methods. Comparing separate designs requires aligning the workload and success conditions, and making explicit up to which stage the same assumptions were shared.
The official capability table also has boundaries. P0 through P3, various estimation types, an RSA-2048 use case, and output to the quantum circuit simulator Stim all have working examples. Meanwhile, features like dynamic codes, code switching, concatenated codes, and mechanisms for further inspecting detection results remain preview-stage capabilities—types and functions exist in the package, but without execution tests or usage examples. The existence of an API is not proof of a complete, verified execution path.
Don't mistake 150,000 qubits and "7x" for real hardware performance
Diraq and Iceberg Quantum mapped a quantum chemistry algorithm called Pinnacle onto silicon spin qubits and presented a target model using roughly 150,000 physical qubits for 1,000 logical qubits. CUDA-Q Logical's estimate, incorporating hardware constraints, reportedly matched the physical qubit count from the Pinnacle paper to within 5%. They also ran numerical simulations that included noise from shuttling—the process of moving qubits.
What this verified is the ability to reproduce a design model through a separate computational path and to add device-specific assumptions. It is not the outcome of actually building a device with 150,000 physical qubits and operating 1,000 logical qubits. Manufacturing yield, control wiring, calibration, and long-term stability cannot be confirmed by model agreement alone.
As a case study with Fermilab, NVIDIA states that a task that previously took roughly five months to build a dedicated framework was shortened to three weeks using CUDA-Q Logical to explore combinations of error-correction schemes. Comparing durations alone gives roughly a 7x figure, but what shortened was the design workflow, not the execution time of quantum circuits. The public materials do not detail the target task, team size, comparison conditions, or reproduction steps in depth, so this cannot be generalized into a productivity rule.
The value these two figures demonstrate lies less in improved hardware performance than in the ability to re-compare design proposals within a common framework. Conversely, reading this as software alone reducing the qubit count on the same device tenfold, or increasing computation speed sevenfold, would be going too far.
QUOPS measures circuit shape and speed, not qubit count
Researchers from Sandia National Laboratories, Quantinuum, NVIDIA, and others proposed "QUOPS," a metric for measuring the effective capability of quantum computers, in arXiv:2609.12146. The circuit alternates layers of arbitrary-angle Pauli rotations and CNOTs, varying width w and operation scale s independently. A shape is deemed successful if the average process polarization can be confirmed at or above 1/√e—roughly 61%—at a 95% confidence level, and the score is the largest successful scale within the range from w² to w³.
A second axis is throughput per second. The sample count increased to verify the success rate, and runs discarded through post-selection, both feed into the speed figure. If a large circuit can be run once but requires enormous numbers of trials to obtain a result, this design does not overestimate its practical capability.
| Configuration | QUOPS score | Throughput per second | Circuit width |
|---|---|---|---|
| Google Willow | 216 | 2.0×10^7 | 6 |
| IBM ibm_boston | 204 | 3.1×10^5 | 6 |
| Quantinuum H2-1 | 1,320 | 353 | 12 |
| Quantinuum Helios-1 | 1,504 | 303 | 16 |
| Helios-1, Steane [[7,1,3]] logical implementation | 40 | 4.9 | 4 |
In QUOPS measurements, physical-qubit machines do not show matching rankings between score and throughput, and the small-scale logical implementation on Helios-1 scored 40 QUOPS at 4.9 QUOPS per second. The benchmark is designed to read, on separate axes, whether a large circuit can be run at all and how fast that can be done.
This table is not a general-purpose machine ranking. Connectivity, compilation, and physical modality differ, and the logical implementation is a small-scale test using at most 8 encoded logical qubits. The Steane code was chosen not because it offers optimal performance, but because it is simple to implement. The paper itself is also a pre-peer-review preprint submitted on September 10, 2026.
The QUOPS paper converts the resources needed for RSA-2048 factorization and computing the active site of the nitrogen-fixing enzyme cofactor FeMoco, estimating that roughly five orders of magnitude of capability increase are needed beyond current devices. However, these are not results from directly running these applications on real hardware. An assumption is involved in translating Toffoli-centric circuits into Pauli-rotation-centric QUOPS circuits. Also, while error mitigation can boost the score roughly 3–11x in the case of 1% polarization, throughput per second drops by 3–4 orders of magnitude. If the score alone is cited in isolation, the cost of sampling disappears from view.
Classical GPUs enter the error-correction control loop
Error correction cannot be completed inside the quantum chip alone. Error syndromes measured by the device must be sent to a classical computer, a decoder must interpret their meaning, and correction information must be returned in time for the next quantum operation. As codes grow larger, measurement data increases, and the allowable latency is constrained by both the device and the procedure.
P4 of CUDA-Q Logical represents instruction dispatch, transfer of measurement results, decoding deadlines, and feedback as a control plan. One execution path for this is cudaq-realtime, which invokes remote procedures from the quantum control system to processing on CPUs or GPUs, and returns results via mechanisms such as shared ring buffers. NVQLink, as a connectivity specification linking the quantum processor and GPU computing infrastructure, supports this round trip.
The two should not be confused. CUDA-Q Logical is the compiler layer that builds the control plan; cudaq-realtime is the execution path that runs it. The published latency figures also measured the communication and control of specific individual configurations—they are not a guarantee that any arbitrary code or decoder will run within deadline.
Even so, NVIDIA's positioning becomes visible. Without manufacturing quantum processors itself, the company can consolidate simulation, compilation, classical-side decoding, and networking into a shared framework. This is an interpretation drawn from the role division among CUDA-Q Logical, cudaq-realtime, and NVQLink, and it does not constitute a definitive statement about NVIDIA's overall business strategy.
Closing the loop between model and hardware
Whether CUDA-Q Logical takes root as a shared framework will not be decided by the number of partner companies. The first requirement is that third parties can reproduce the same P0 program mapped onto different codes and devices, and identify which assumptions produced the resource differences. Next, it must be confirmed how closely the time and utilization predicted by SCHEDULE match real hardware measurements, and how QUOPS scores and throughput feed back into design changes.
Further, dynamic codes, code switching, and concatenated codes—currently without usage examples—need to move into execution testing, and it must be verified on real hardware whether P4's control plans can meet deadlines across multiple vendors' control systems and decoders. Once peer review, reproduction experiments, and a closed loop with real hardware are in place, CUDA-Q Logical could become not a machine that predicts future quantum computers, but a shared design language that lets us trace even the reasons a prediction went wrong.